Niranjan Girhe
Seeking a thesis-based master’s position · Game AI, procedural generation, on-device models
About
I want to study how small AI models running on a player’s device could help non-player characters (NPCs) behave more naturally. These characters would remember past interactions and use that history to respond to the player’s actions and to events in a changing game world.
I’m also interested in worlds that change in response to how someone plays. Those changes need to make sense within the game’s rules and history. The practical challenge is to run these models alongside the game, within the device’s available memory and computing capacity.
I’m looking for a thesis-based master’s position to pursue this work. I’ve built five prototypes to explore parts of it so far. The most recent is a physically simulated character whose reactions to surprise events are chosen by a decision model running on my own computer. My background includes a game-based research project at Ontario Tech University, Canada, and work on LLM systems in industry since 2023.
Inspiration
Some of this interest comes from getting bored with repetition in games. In Ghost of Tsushima, fighting the same types of enemies began to feel repetitive to me. Playing Cities: Skylines, I often felt that the traffic behaved unintelligently. These experiences made me curious about enemies that adapt to how I play and simulated drivers that make better decisions as traffic conditions change. I want to explore whether those responses could keep a game engaging over repeated sessions.
Code Bullet’s How I made AI Generated Rick and Morty Episodes (2023) connects ChatGPT to Unity, where 3D characters act out generated scripts with text-to-speech voices. Seeing generated dialogue and actions work together made me think about how LLMs could make NPCs more interactive. A character could respond to what a player says and does, with the conversation influencing its next action. I want to test whether small models on the player’s device can support those interactions during play, as the situation changes.
Learning a bit about Rockstar’s technology also shaped this interest. In the ragdoll discussion from 4:50 in Corridor Crew’s breakdown of the GTA 6 trailer (2026), they describe Euphoria, the real-time counterpart of NaturalMotion’s film tool Endorphin. In their example, a character hit in one leg tries to balance on the other, then raises its arms to protect itself as it falls. A control system selects these responses from states and rules while the physics simulation runs. What interests me is how the character’s physical situation determines its response. I want to explore a similar connection between an NPC’s experiences and its behaviour: how what it remembers, together with what is happening now, could guide its dialogue and its choice of actions within the game’s rules. I built a small version of this idea in Sketch I, where a decision model chooses the character’s reaction.
Research questions
- Q1
Which decisions can run locally? A model running locally has to share resources with the rest of the game. I would compare its decisions with scripted behaviour, measure response time and memory use, and check how it affects frame times under different CPU and GPU loads. Those measurements would help identify which decisions justify the cost and how often the model can run.
- Q2
How should an NPC use its memory? The model would receive a character’s interaction history, the current world state and the actions the game allows. I want to test whether that information is enough to keep its decisions and dialogue consistent with what has happened, even as the world changes.
- Q3
When should the world adapt? I’m interested in a system that adjusts terrain, encounters and pacing in response to how someone plays. I want to understand when to make those changes so the world stays recognisable and its history still makes sense.
- Q4
How does adaptation feel to the player? Player studies would compare adaptive and scripted versions over repeated sessions. I’d ask whether adaptation makes the game more enjoyable, whether the characters feel believable and whether the encounters stay engaging. Fairness matters too, including whether players can understand the changes well enough to learn from them.
- Q5
When should the game fall back to a script? I want to check how well a model’s confidence estimates match the quality of its decisions. That could help the game choose between accepting an answer and using an authored response. Player studies would also check whether the switch is noticeable.
- Q6
Can specialised decision models support real-time gameplay? Typed decision models return choices, scores or probabilities that game code can use directly. I’d test TypeSafe AI’s hosted Jev and the open-source Laya on NPC actions and changes to the world, alongside GLiClass as an open-source classification baseline. Small language models such as Qwen3-0.6B and SmolLM2-1.7B would provide a comparison. Can these approaches make consistent decisions quickly enough as the game state changes?
Proposed approach
One possible approach is to start with a single prototype and use its existing rules as a baseline. I could then compare different models on the same tasks before testing how they change the player’s experience.
- Runtime tests: compare small, quantized LLMs and typed decision models with the existing rules in one prototype. Measure decision quality, response time and memory use, and check how running each model affects frame times.
- Local and cloud comparison: run the same decision tasks with local models, cloud-hosted LLMs and Jev’s hosted API. Compare decision quality, end-to-end latency and cost, and test how the game handles delayed responses or a lost connection.
- Memory and actions: pass the relevant history and game state to the model, and limit its choices to actions the game supports. Test whether a confidence threshold reliably identifies when the game should fall back to a script.
- Changes during play: build a game director, a system that adjusts encounters and pacing from observed player behaviour. Check that its changes respect the world’s rules and earlier events.
- Player studies: ask players to try the adaptive and scripted versions over repeated sessions. Compare how much they enjoy each version, how believable and fair it feels, and how easily they learn to respond to changes.
Prototypes
The first prototype runs typed decision models inside a physics simulation in Unity, and the clips below are recorded from it. The other four began as hand-written rules and simulations, and two of them now also have local-model prototypes. Each of those four has an interactive version you can try below.
Sketch I. Physical reactions chosen by a decision model
This is a physically simulated character in Unity that reacts to surprise events: a box falling toward it while it sits on a bench, or a ball thrown at it while it stands. Its body is 15 rigid parts joined by motors, and it never plays an animation clip. Every movement comes from the physics simulation.
When the simulation senses an event, it describes it in one sentence, such as “A heavy object (about 12 kg) is falling toward the head, about 0.4 s until impact.” A typed decision model reads the sentence and chooses one of seven reactions, such as bracing, dodging sideways or curling up, along with how stiff the muscles should be. The character tenses briefly while it waits, like a flinch. If no answer arrives within 200 ms, hand-written rules decide instead. I compared Laya and GLiClass, both used without fine-tuning, with the rules and with a fixed reaction, on the same 30 events in each scene.

View more recorded clips


Results.
- A decision from Laya took 47 ms (median) and 1.7 GB of video memory; GLiClass took 15 ms and 0.6 GB. The rules took under 0.1 ms. Only 1 of 116 model decisions missed the 200 ms limit.
- On the CPU, Laya took about 1.8 s per decision, too slow for the 200 ms limit; GLiClass took about 44 ms.
- Without fine-tuning, the models didn’t use the details of the event. On the bench, Laya curled up and GLiClass dodged every time. Standing, each spread its answers over three to five reactions, but not in line with the object’s weight, the time left or where it would hit.
Laya’s model card says its base checkpoint is meant to be fine-tuned, and the simulation can label training examples itself by trying each reaction and keeping the one that worked best. A lighter option is a small policy trained with reinforcement learning that reads the event’s numbers directly. It could output the values that drive the body, so reactions would be generated rather than picked from a list (Q1, Q6).
Sketch II. Memory and NPC decisions
Mira is a shopkeeper who remembers her interactions with the player. If someone helps her and later steals from her, both events affect her response and the price she charges.
I use hand-written rules to score her responses and prices, with templates for dialogue. Depending on the player’s history, Mira can offer a discount, charge more or refuse to sell altogether. She can also offer a free apple after repeated help, share a quest or warn the town guards.
I have built a separate prototype that runs this with local AI. A typed decision model, GLiClass, gets her history and the current game state and scores each action the game supports. A small language model, Qwen3-0.6B through Ollama, only turns the chosen action into what she says, so it can’t change her decision or her price. If either model is missing, slow or returns something unusable, the game falls back to the rules and templates above. I timed each step over a 50-turn game on my own computer (an RTX 4070 SUPER), and compared Qwen3-0.6B with SmolLM2-1.7B.
You carry Mira's crates for two days, buy an apple, help again, and come back to buy another.
- d1help carry crates
- d1help carry crates
- d1let a day pass
- d2buy an apple
- d2help carry crates
- d2let a day pass
- d3buy an apple
Fresh apples! Two coins each.
- Price: 2 coins, always
- Latest action only
For you? One coin. You've carried enough crates.
- Price: 1 coin
- Offers you a quest: find her lost cart
- 1Read her memorytrust +55annoyance 0fear 0buy ×2help ×3
State used for this decision
{ "npc": "Mira, fruit seller", "day": 3, "trust": 55, "annoyance": 0, "fear": 0, "remembers": { "buy": 2, "help": 3 }, "broken_apologies": 0, "last_event": "buy" } - 2Score the available choicesscoreWhat price should she charge you?1 coin89%2 coins10%3 coins0%no sale0%
1 coin at 89%: above the 60% needed to act
choiceHow should Mira treat you?welcome96%serve as usual2%be wary2%refuse to sell0%call the guards0%↑ 60% needed to actyes / noWill this player steal from her again?2% yes · 98% no - 3Act, or fall back
Price decision: 1 coin · response: welcome. The response uses the game’s predefined options.
- 4Put it into words
In the proposed system, a small language model would express the selected decision as dialogue. This prototype uses templates for that step.
Without memory, Mira charges two coins every time. With memory, she charges the regular customer one coin and the known thief three. For the friend who stole, neither price reaches the confidence threshold, so she returns to the usual two coins. The confidence scores are assigned by hand-written rules; they do not measure a trained model’s reliability. Dialogue comes from templates.
View measured results from the prototype
| Decisions | Dialogue | Decision | Dialogue | Whole turn | First turn | Generation |
|---|---|---|---|---|---|---|
| Built-in rules | Authored lines | 0.0 ms / 0.1 ms | 0.0 ms / 0.0 ms | 0.0 ms / 0.1 ms | 1.2 ms | |
| GLiClass | Authored lines | 61 ms / 121 ms | 0.0 ms / 0.0 ms | 61 ms / 121 ms | 175 ms | |
| GLiClass | qwen3:0.6b | 62 ms / 121 ms | 210 ms / 268 ms | 276 ms / 389 ms | 1.9 s | 318 tokens/s |
| GLiClass | smollm2:1.7b | 61 ms / 121 ms | 179 ms / 302 ms | 262 ms / 363 ms | 2.3 s | 195 tokens/s |
- GLiClass (gliclass-small-v1.0): about 780 MB RAM · loads in 2.8 s, runs on the CPU
- qwen3:0.6b: 3.1 GB VRAM · all of it on the GPU
- smollm2:1.7b: 2.6 GB VRAM · all of it on the GPU
- Game server: 70 to 75 MB RAM
Intel Core i7-13700K (24 threads), 32 GB RAM, NVIDIA GeForce RTX 4070 SUPER (12 GB), Windows 11. Node 23.11, Python 3.11, Ollama 0.30.11; GLiClass on the CPU (CPU-only PyTorch build), Ollama models fully on the GPU. Each setup played the same 50-turn game. No run fell back to the built-in rules or the authored lines.
Results.
- A decision from GLiClass took 61 ms (median) on the CPU, or about 120 ms after a purchase, when the price is scored too.
- A whole turn with dialogue took 276 ms with Qwen3-0.6B and 262 ms with SmolLM2-1.7B. Both ran fully on the GPU, using 3.1 GB and 2.6 GB of video memory.
- Speed is fine, but the choices are not yet. GLiClass picked “welcome” on all 50 turns, even after thefts and a hit, though it did raise her price after the player started stealing. Qwen3-0.6B copied its prompt in 44 of 50 lines; SmolLM2-1.7B wrote new lines in her voice and copied only once.
Sketch III. Adaptive bosses
An enemy boss can become predictable once a player has learnt its attack patterns. I’m interested in one that notices the player’s habits and changes its tactics in response. If a player keeps attacking from behind, the boss might turn to guard its back or sweep its tail, leaving its front less protected.
In this model, the boss has a limited budget for counter-moves. Each has a warning the player can learn to read and a weakness they can exploit. The chart follows twelve attempts, showing how the assumed challenge changes with the player’s habits and the boss’s adaptation.
Mostly attacks from behind, with some dodging. The boss spends 55 of its 100 points countering this player; the rest stays in its base moveset.
- Rear guardSpins round or sweeps its tail when you get behind it.Weakness: Its front is less protected while it guards its back
Within targetAverage predicted challenge is within the target range in later attempts.
The curve assumes that player skill improves with each attempt and counters are more effective against predictable habits. The shaded range is a design target. Player studies would test whether fights in that range feel fair and engaging (Q4).
I have also built this as a playable fight. The player picks a move each round, and every counter shows its warning before it strikes. Between attempts, a typed decision model (GLiClass) reads a summary of how the player has been fighting and scores the four counters, and the boss splits its budget by those scores. A small language model gives the boss a taunt about what it noticed. Built-in rules based on the model above take over when GLiClass isn’t running.
To compare it with a static boss, I wrote five bot players, each with one strong habit (or none), and had each fight both bosses for twelve attempts. Every attempt, the bots get better at reading the warnings and at beating the base moveset. Challenge is the share of health a bot lost in an attempt, or 100% if it lost.
View results from the prototype
| Bot | Static | Adaptive | Won vs adaptive | Where the boss spent its 55 points |
|---|---|---|---|---|
| Attacks from behind | 28% | 42% | 12 of 12 | Rear guard 54, Delayed strikes 1 |
| Fights from range | 30% | 40% | 11 of 12 | Rear guard 27, Charge 22, Delayed strikes 5 |
| Dodges through attacks | 30% | 41% | 12 of 12 | Rear guard 52, Delayed strikes 3 |
| Repeats the same combo | 32% | 35% | 12 of 12 | Rear guard 34, Combo blocking 21 |
| Varies their attacks | 32% | 42% | 12 of 12 | Rear guard 48, Combo blocking 4, Delayed strikes 3 |
The built-in rules made the boss’s decisions. Every bot gets better each attempt at reading the warnings and at beating the base moveset, and attacking from behind is the best answer to the base moveset, so most bots drift towards it and the boss spends more on its rear guard. Challenge is the share of health a bot lost, or 100% if it lost.
Results.
- Against the static boss, challenge fell from 52% to about 30% as the bots learned it; 13% of later attempts were inside the 35–60% target range.
- Against the adaptive boss, challenge settled at about 40%, and 60% of later attempts were inside the target range.
- The bots still won 59 of 60 fights against the adaptive boss, against 60 of 60 against the static one, so it made fights harder without making them unwinnable.
- The adaptive boss was hardest right after the first attempt (60% on average), when it countered a habit the bots couldn’t yet read.
The bots learn the way I told them to, so these results test the design under my assumptions; they don’t measure difficulty or enjoyment. I would need player studies to find out how much the boss can change while giving players a fair chance to learn its counters, and whether those changes keep the fight engaging (Q4).
Sketch IV. Evolving enemy populations
This idea came to me while playing Ghost of Tsushima. I wondered how encounters might change if enemy populations adapted to the tactics a player kept using. Could traits that help enemies survive those encounters become more common over time?
In this simulation, predators and prey pass traits such as speed and eyesight to their offspring, with small mutations in each generation. The traits affect survival and reproduction. Speed, eyesight and agility also cost energy, so there are tradeoffs in which traits a creature can sustain.
I’d like to test this idea over successive playthroughs or seasons in a game. There is no player in the simulation; the possible adaptations in Table 1 are ideas for a game.
| If the player… | Enemies could evolve… | Related result or rule in Fig. 3 |
|---|---|---|
| Stays at a distance, out of sight | Longer vision range, with a narrower field of view | Predator vision range increased in 5 of 10 runs; there was no consistent trend |
| Outruns them | Greater speed and tighter turns | Both species got faster in nearly every run |
| Dodges and weaves through attacks | Better tracking before committing to a strike | Predators developed a wider binocular zone in 7 of 10 runs |
| Exploits one weakness over and over | A counter that exposes another weakness | The simulation assigns energy costs to speed, eyesight and agility |
- 1Run the simulation (try 20× speed)
- 2Click any creature to inspect it
- 3Watch how each species' eyes change
Pale = field of view · dark core = binocular (depth) zone · dashed = at start · facing right
| Prey | Predators | |
|---|---|---|
| Top speed | 1.50 | 1.53 |
| Field of view | 260° | 261° |
| Binocular zone | 65° | 64° |
| Vision range | 109 | 111 |
| Turn radius | 10.7 | 15.4 |
| Body size | 1.00 | 1.20 |
| Generation | 0 | 0 |
Click a creature to inspect its genome.
Each creature inherits five genes: speed, eye size, eye placement (side-facing vs front-facing), turn rate and body size. Speed, eyes and agility cost energy every tick; offspring mutate slightly. Shaded cones show each field of view, with the darker core marking the binocular zone. Trait changes emerge from survival and reproduction under these rules.
View results from 10 recorded runs
Predators developed a wider binocular zone in 7 of 10 runs (65° → 80° on average). The simulation makes pounces more likely to succeed when prey is in this zone, where both eyes can see it. Prey eye placement showed no consistent trend.
Both species got faster (predators in 10 of 10 runs, prey in 9). Prey vision range decreased in 9 of 10.
Run 1 of 10, sampled every 150 ticks. Population sizes fluctuate; both species persist in this run.
Results.
- Predators developed a wider binocular zone in 7 of 10 runs (65° → 80° on average).
- Prey vision range decreased in 9 of 10 runs.
- Predators got faster in 10 of 10 runs; prey in 9 of 10.
In a game, these population changes would need to work with the behaviour of individual enemies. I’d like to test whether a game director can coordinate the two, and what that does to encounters over repeated play (Q3).
Sketch V. Traffic that remembers
The idea for this prototype came from playing Cities: Skylines II. I wondered whether commuters could learn from earlier journeys and use that experience to anticipate congestion before it appears on a live traffic map. This simulation explores that question in a small city.
There are two copies of the city, each with 420 commuters. In one, drivers use current traffic conditions alone. In the other, they combine memories of previous journeys with live updates. Adding roadworks in the interactive version disrupts the same street in both cities.
Drivers with memory store travel times by road and time of day. They use that history to choose when to leave and which route to take, then consult live updates if a road is much slower than expected.
- 1Run the mornings
- 2Click any street to start or stop roadworks
- 3Compare what each kind of driver knows
420 commuters cross the river to work each morning. On the left, everyone follows the live map. On the right, drivers also remember past trips and plan around the rush.
View results from 6 recorded runs
The summary figures average days 15–21 across 6 runs. Delay is measured against the fastest trip on empty roads. During roadworks on Central Bridge (days 22–28), average delay rises to 45 minutes with live routing alone and 39 minutes with memory.
Results.
- Average delay per commute in week 3: 6 min with memory, 18 min with the live map only.
- Average delay during unexpected roadworks in week 4: 39 min with memory, 45 min with the live map only.
- Drivers who had to reroute mid-trip: 2% with memory, 52% with the live map only.
These results come from routing rules and stored travel times. I would use them as a baseline for testing a small model that summarises travel patterns or revises a plan after an unexpected disruption. Any improvement in its decisions would need to justify the model’s runtime cost (Q1).
Background
Education
- 2019–23
B.Tech, Computer Engineering, MIT Academy of Engineering, Pune. CGPA 9.74 / 10.
Publication
- 2022
N. Girhe, D. Chaudhari, P. Channe and A. Bhute. Shetkari Mitra App: An Application to Maximize the Profit of Farmers. In Advances in Communication, Devices and Networking, Lecture Notes in Electrical Engineering, Springer, pp. 111–127.
Award
Research and work
- 2023–present
Software Engineer, Impactility
- Built a self-sovereign identity system to W3C DID standards, with a credential issuer, verifier and wallet that support zero-knowledge proofs (Next.js, NestJS).
- Led a rebuild of the ServCare platform: a React web app, a React Native mobile app, AWS infrastructure, CI/CD, and App Store and Play Store releases.
- 2023–25
Full Stack Engineer (contractor), Shell
- Built an LLM-based search platform for internal code repositories, with role-based access and deployment on Azure.
- Built middleware that connects Shell’s EV-charging (OCPP) infrastructure to partners such as J.P. Morgan, using Kafka streaming.
- Built a digital product passport prototype with Solidity and verifiable credentials.
- Built an internal events platform that staff can update without writing code.
- 2022
Research Intern, Software Engineering & Education Research Lab, Ontario Tech University, Canada (MITACS Globalink)
- Worked on ThreadedPaws, a serious game from the lab’s research on game-based learning in computer science, supervised by Jeremy Bradbury and Michael Miljanovic. The game teaches thread interleavings, data races and deadlocks.
- Designed new levels that each isolate one concurrency problem.
- Built an in-game tutorial that introduces the concepts step by step.
- Refactored the Unity (C#) code so new levels are easier to add.
- 2021–22
Lead researcher, Shetkari Mitra, MIT Academy of Engineering
- Studied whether a phone photo of soil, together with location data, is enough to estimate soil health (NPK and organic carbon).
- Built the model into an Android app for farmers, designed to run on limited hardware.
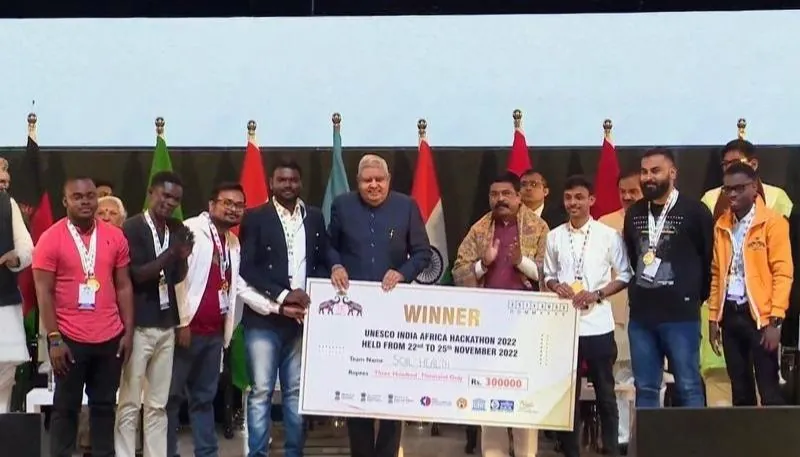
- Published by Springer; won the UNESCO India Africa Hackathon 2022.
Tools: Unity and C#, Android, TypeScript simulations, LLMs (RAG, tool use, MCP).
Contact
I’d welcome a conversation with researchers working on game AI, procedural generation or interactive systems about a possible master’s thesis in your group.
Email: niranjangirheindia@gmail.com
CV: view or download